Your prompt passes all your tests. You ship it to production. Then a user types something you never considered, and it fails spectacularly.
This isn't an edge case. It's the norm.
According to LangChain's State of Agent Engineering Report, 32% of organizations cite quality as their #1 barrier to production AI. Even more telling: only 52% run offline evaluations before deployment. Many teams are essentially flying blind.
Traditional software testing doesn't work for non-deterministic AI. You can't just write a unit test and call it done. Prompts behave differently across models, contexts, and edge cases you've never imagined.
The solution? More diverse test cases. And that's where the community comes in.
Why Test Cases Matter
The shift from "prompt and pray" to evaluation-driven development is happening industry-wide. Anthropic's engineering team puts it directly:
"Start with 20-50 tasks drawn from real failures." Anthropic Engineering
Test cases transform prompt engineering from art to science. Here's what they unlock:
Regression detection. Catch when model updates break existing functionality before your users do.
Faster model adoption. Teams with established evaluations assess new models in days, not weeks.
Deployment confidence. Know your prompt handles critical inputs before they reach production.
Measurable progress. Track your prompt's performance over time with quantifiable metrics.
Every test case you add creates a safety net that catches future failures before they reach production.
The Rise of Community-Driven Evaluation
The AI industry is moving toward crowdsourced benchmarks. And for good reason.
Kaggle recently launched Community Benchmarks, enabling developers to create and share evaluation datasets.
LMArena has built the world's largest repository of human preferences for comparing language models, with millions of community-submitted comparisons.
LegalBench assembled 162 legal reasoning tasks entirely crowdsourced from legal professionals.
Why does crowdsourcing win?
-
Diversity of edge cases. Experts miss what users encounter daily. A thousand contributors think of a thousand different ways to break your prompt.
-
Real-world scenarios. Community inputs reflect actual usage patterns, not hypothetical edge cases dreamed up in isolation.
-
Continuous evolution. As models improve, benchmarks need to evolve. Communities adapt faster than any single team.
No single team can anticipate every way users will interact with their prompts. But a community can.
Introducing LunaPrompts Community Test Cases
Today, we're launching Community Test Cases on LunaPrompts.
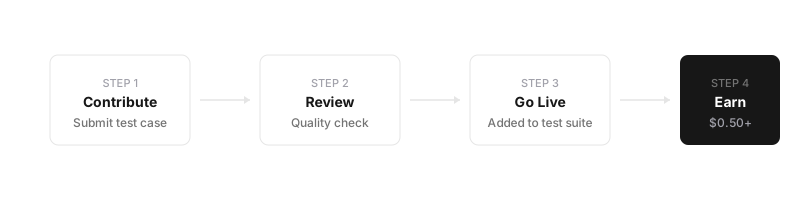
How It Works
-
Contribute. Submit an input and expected output for any challenge on the platform.
-
Review. Our team reviews submissions for quality, uniqueness, and edge-case value.
-
Go Live. Approved test cases become part of the challenge's official test suite.
-
Earn. Get credits when approved, plus bonus credits when your test catches failures.
Example Test Case
For a sentiment analysis challenge, here's what makes a test case valuable:
{
  "input": "I'm feeling a bit meh today",
  "expected": "Neutral",
  "rationale": "Ambiguous slang that requires nuanced understanding"
}
This input trips up most prompts. It's not clearly positive or negative, uses informal language, and requires cultural context. That's exactly what we're looking for.
The Reward System
We believe great test cases deserve recognition. Here's how you earn:
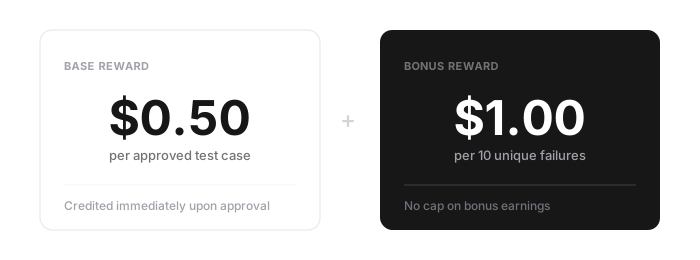
How earnings work:
- Submit a test case → get reviewed within 48 hours
- Approved? $0.50 credited to your account immediately
- Your test catches users off guard? $1.00 bonus for every 10 unique failures
What's a unique failure? When a different user's prompt fails your test case, that counts as one unique failure. If the same user fails multiple times, it only counts once. This rewards test cases that challenge a wide range of approaches, not just one person's mistake.
What you can do with credits:
- Redeem for API keys (OpenAI, Anthropic, and more)
- Unlock premium challenges
Want something else? Email us at contact@lunaprompts.com. We're open to suggestions.
We cap contributions at 5 test cases per challenge per user to keep quality high and give everyone a fair shot.
Recognition for Contributors
Credits are just the beginning. We want to celebrate the people who make our community stronger.
Finding edge cases that break prompts is a real skill, one that's increasingly valuable as AI moves into production. It requires understanding how language models think, anticipating failure modes, and thinking creatively about inputs others miss. This is the kind of expertise that sets great prompt engineers apart.
We want to recognize and showcase that skill.
Coming soon: Contributor Leaderboard. We're building a dedicated leaderboard to showcase top test case contributors. You'll see who's finding the trickiest edge cases, whose tests have caught the most failures, and who's made the biggest impact on challenge quality.
Top contributors will get:
- Public recognition on their profile and the leaderboard
- Contributor badges that highlight your impact
- Early access to new features and challenges
- Shoutouts in our community channels
Your contributions matter, and we want everyone to know it.
The Virtuous Cycle
Your contributions create a flywheel that benefits everyone:
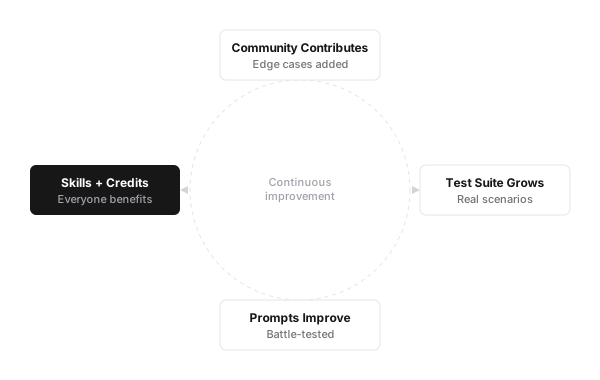
When you find an edge case that breaks prompts, you're helping every future user write more robust solutions. The community grows stronger together, and you earn rewards along the way.
Get Started
Ready to battle-test some prompts?
- Pick any challenge on LunaPrompts
- Click "Contribute" in the test cases section
- Submit your edge case with expected output
- Watch your credits grow as your test catches failures
Every test case you contribute makes the entire platform more robust. Let's build better AI together.
Have questions about Community Test Cases? Join our Discord or connect with us on LinkedIn.