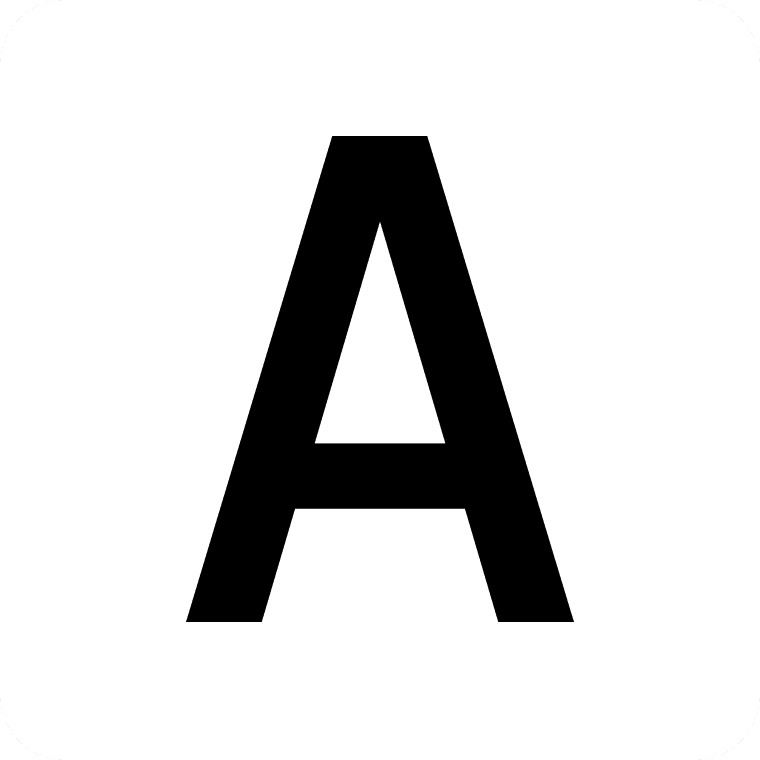
anam is a provider selector, not a versioned model identifier.
Access
POST https://api.anam.ai/v1/auth/session-token with personaConfig.voiceDetectionOptions.sttProvider=anam and an explicit supported languageCode. Only full-pipeline sessions; no standalone transcription endpoint verified.
Regions
Production inference/media on CoreWeave in Spain/EU and US East. Enterprise can select eu/us engine regions with strict or preferred routing. External providers and stored assets are separate.
Explicit incompatible provider-language pairs are rejected. If inherited organization language becomes incompatible, the session may use the platform default provider without modifying the saved configuration.Source for languageFallback (opens in a new tab)
recognitionControls
endOfSpeechSensitivity: 0–1 (Anam default 0.5); speechEnhancementLevel: 0–1 (default 0.8). Silence timeouts are pipeline controls, not transcription model token limits.Source for recognitionControls (opens in a new tab)
Endpoint pricing has not been collected. Check the provider for applicable rates.
Data & enterprise terms
Default recordings retained up to 30 days; reports/transcripts/analytics remain until deleted. Enterprise ZDR keeps session content in volatile memory but excludes source avatar images, knowledge files and operational/account metadata. Applicable terms prohibit customer-content training, subject to any separate written agreement described in governance.
Caching can reuse earlier input processing. Availability, lifetime and billing depend on the endpoint. A cache hit still generates a new response.
01 / INITIAL INPUTProcess & retain
The system processes eligible input and retains reusable state.
02 / LATER REQUESTCheck available state
Reuse depends on matching input, session state and the cache policy.
03 / CACHE HITReuse & generate
Reusing state can reduce repeated work. Any charges follow the billing rules below.
Anam managed transcription
Not verified
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
How it works
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
Minimum reusable input
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
Lifetime & refresh
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
How to enable it
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
Usage fields
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
Billing rules
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
Limits & data boundaries
Not collected
No provider prompt-cache API or model-specific cached tariff has been established. Saved avatars and internal inference state are separate.
No verified cache rate for this endpoint. An empty rate is not a zero charge.
Caching reviewed 14 Oct 2026
What the measurements say
No benchmark observations have been added for this model. We do not turn a vendor description into a performance score.
Latency and throughput depend on the host, request size, reasoning settings and load. There is no measured speed or global usage figure in this record.
The record behind the model
Why it is included
Documented Anam-hosted speech-to-text service selectable with sttProvider=anam. Public documentation does not identify its underlying weights or establish a privately trained base model; this record is explicitly a managed component.